About the project
I wanted to sort a stream from multiple channels without copying every post by hand. I built a pipeline that shows why a post matched, what OCR read and where it was sent.
I collect new messages from the MAX folder in Telegram. On the server, each post goes through classification, filters and source attribution. Matching posts go to MAX channels with their original text and attachments. The working interface shows model scores, OCR, labels, errors and delivery history.
What sets the implementation apart
The original is not rewritten. Post text and text on media are classified separately. A filter checks model scores and assigns a plain label from my dictionary. A post can go to several channels. Saved message IDs and attempt history help investigate delivery errors.
Application-code composition
Shares use Git application-file bytes at pinned revisions. Each file belongs to one subsystem under scripts/generate-stack-share.mjs rules; tests, assets, dependencies and generated files are excluded. Rounded to 0.1%. This describes code composition, not proficiency.
- Corpus labels were assigned by Codex. Model measurements describe agreement with those labels, not independent human accuracy.
- The beginner and humor routes are experimental. Beginners: 57/65 test matches; OCR humor: 92/104 validation matches. The agreed quality gates were not passed.
- OCR does not understand an image without text, listen to audio or inspect the whole video. Reading errors need review.
- Media over 100 MB and unavailable album parts block automatic readiness. The interface contains stopped cards.
- Screenshot counters and timings are a state snapshot, not a performance guarantee.
Screenshots, diagrams and source evidence retain their original language; captions and descriptions are translated.
Architecture and diagrams
- A new_only collector receives new messages. The old unprocessed buffer is not processed automatically.
- Separate processes: web, collector, coordinator, TF-IDF, MiniLM, OCR and the MAX sender. Queues and results are stored in PostgreSQL.
- RapidOCR reads images and static video previews. OCR text is not appended to a publication.
- A missing score stays unknown. Filters support categories, subcategories, model features, length and nested AND / OR / NOT.
- The original post is sent with media and a Source link. There is no additional extracted-links block.
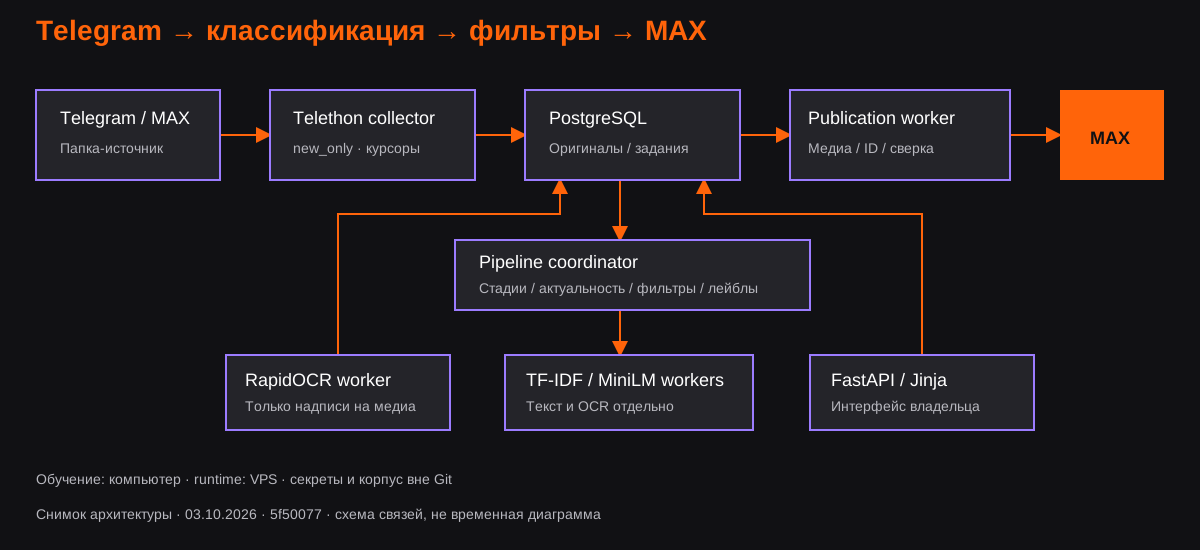
Code map: files and dependencies
This map is tied to version 5f50077babfe. The table lists the screen or API, related module and data.
| Feature | Screen / API | Module | Data / verification |
|---|---|---|---|
| Collection | Telegram MTProto | app/live_collector.py; app/collector.py | new_only boundary, chat cursor, originals and media |
| Stage transitions | /pipeline | app/pipeline_coordinator.py; app/content/source_marking.py | PipelineEntry, text freshness, labels and readiness |
| Models | /api/pipeline/{id}/taxonomy | app/taxonomy/jobs.py; app/taxonomy/inference.py | Jobs, complete scores, version, input_source, history |
| OCR | /api/pipeline/{id}/ocr | app/ocr/worker.py; app/ocr/engine.py; app/ocr/media.py | OCR run, lines, confidence, cache, media hashes |
| Filters and labels | /pipeline/filters; /marks | app/content/selection_rules.py; app/content/selection_filters.py | Condition tree, rule versions, assignments and evidence |
| MAX | /publication | app/publication/worker.py; app/publication/service.py | Routes, delivery jobs, attempts, IDs and delivery verification |
Using the code map
- Before making a change, find the feature and trace its links to the API, state and storage.
- Check inputs, errors, repeated events and dependent workflows.
- After making a change, update the map and affected diagrams alongside the code.
- Run the related checks and link the new evidence to the source version.
Workflows and API
- Open the public MAX channels and an example repost.
- With owner access, open the board: Received → Sorted → Filtered → Source attribution → Ready.
- Open a card and select post text or OCR as the result input. Compare saved runs.
- Open a filter and inspect its model, conditions, label and matching preview evidence.
- In MAX history, inspect the destination, delivery state, saved link and errors.
Verification of the published version
CI: Tests and runtime build ↗ · 5f50077b · this demo's version · 2026-10-03
- GitHub CI for the pinned revision completed successfully; the link below refers to 5f50077.
- The real overview, board, filter, text/OCR cards and delivery history were opened while preparing this page.
- The working interface marks the initial 9 × 20 batch as confirmed. Saved publication links are available.
These checks apply to the listed version. Business metrics and model quality on an independent dataset were not measured.
Measurements
- Nine MAX channels are connected. The initial batch contains 180 publications, 20 per channel. Sending of new matching posts is enabled.
- The captured history includes later deliveries. The publication count changes as new messages arrive.
Running and operating
Training corpora and secrets are outside Git. Model artifacts and pinned Docker images go to the VPS; training runs on the computer.
Settings are read in app/config.py. The collector uses the Telegram session; the sender uses the MAX token. Public material contains no keys or private conversations.
MAX_PUBLISHER_ENABLED controls the separate sender. Old LLM, rewrite and Telegram publishing paths are not part of the current route.
Attempt history is stored in the database. An uncertain delivery is reconciled before a retry to avoid duplicates.
Stack
| Python / Telethon | Collection from the user’s MAX folder in Telegram |
|---|---|
| FastAPI / Jinja / JavaScript | Working interface, protected APIs and board refresh |
| PostgreSQL / SQLAlchemy / Alembic | Originals, jobs, filter versions, labels, OCR and deliveries |
| TF-IDF / scikit-learn | Default automatic classification |
| MiniLM / PyTorch | Local training and manual comparison on the server |
| RapidOCR / ONNX Runtime | Reading text on media in a separate worker |
| MAX Bot API / httpx | Attachment upload, sending and message verification |
Materials and source code
Repository history starts on 16 June 2026. Current workflow and captures: 3 October 2026.
The evidence archive retains its original language.